9series

ATLAS

Telecommunications Agentic AI Test Automation
313Test cases run end to end in one regression
2×Fewer runs failed by the tool itself
10×Faster automated OTP sign-in
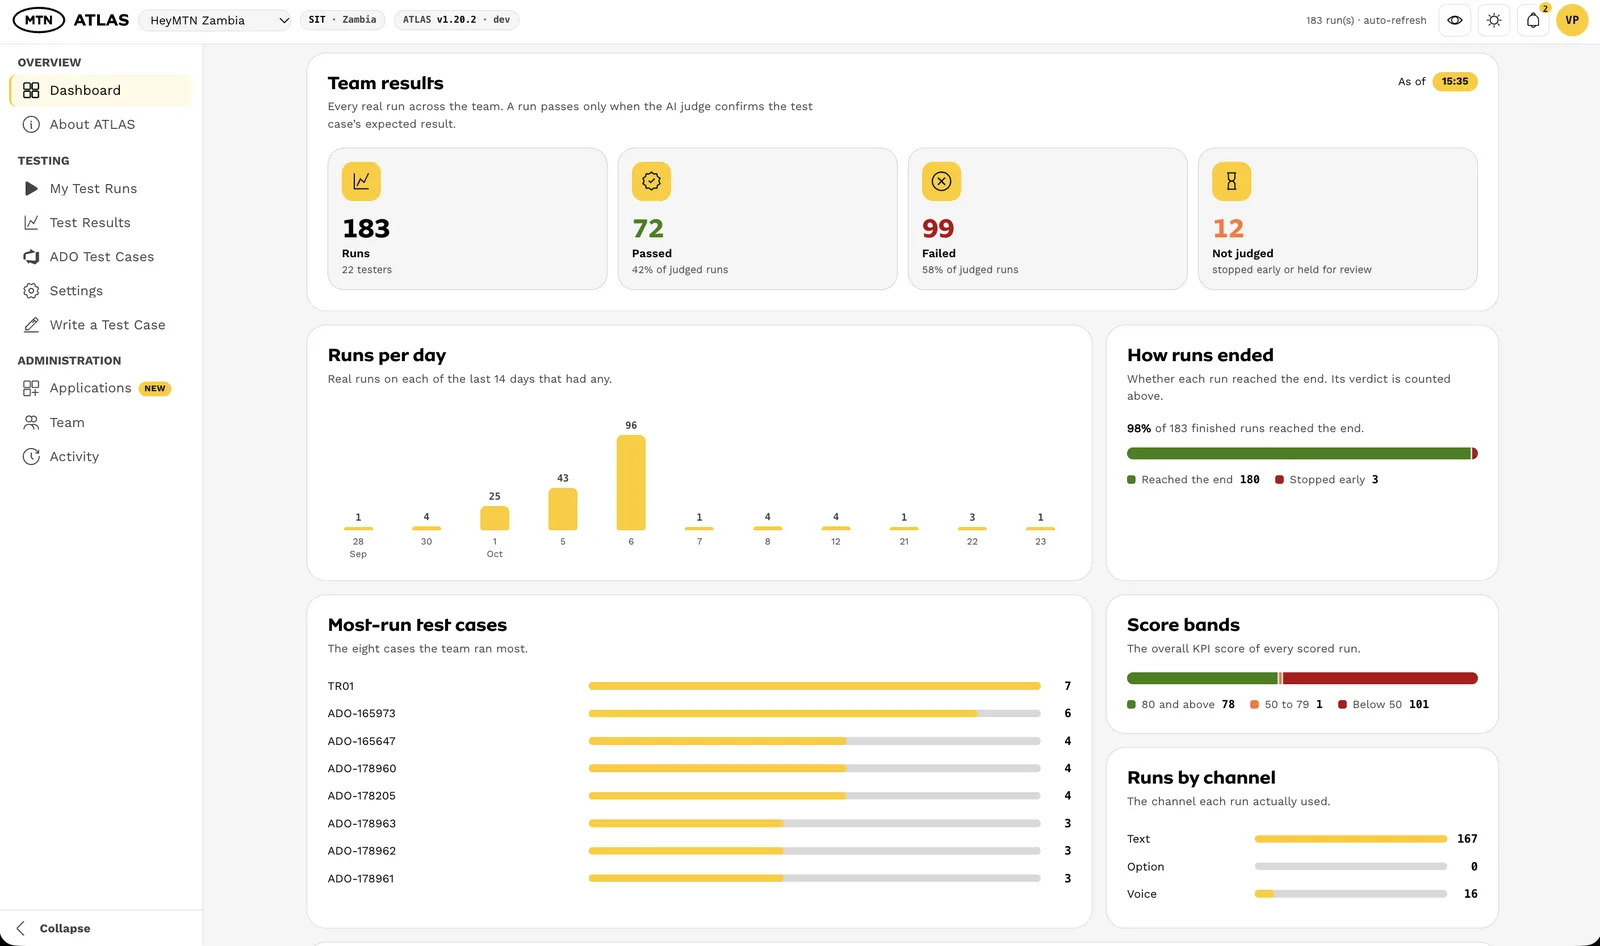
ATLAS dashboard showing team test results, runs per day and score bands

Project Overview

A leading pan-African mobile network operator was launching an AI assistant inside its consumer app, covering balances, bundles, airtime, loans and support by text, tap and voice. We built ATLAS, an agentic AI test platform that reads each Azure DevOps test case like a tester, drives the real app, collects the evidence, judges the outcome against the case and posts the result back, so testers review results instead of clicking through them.
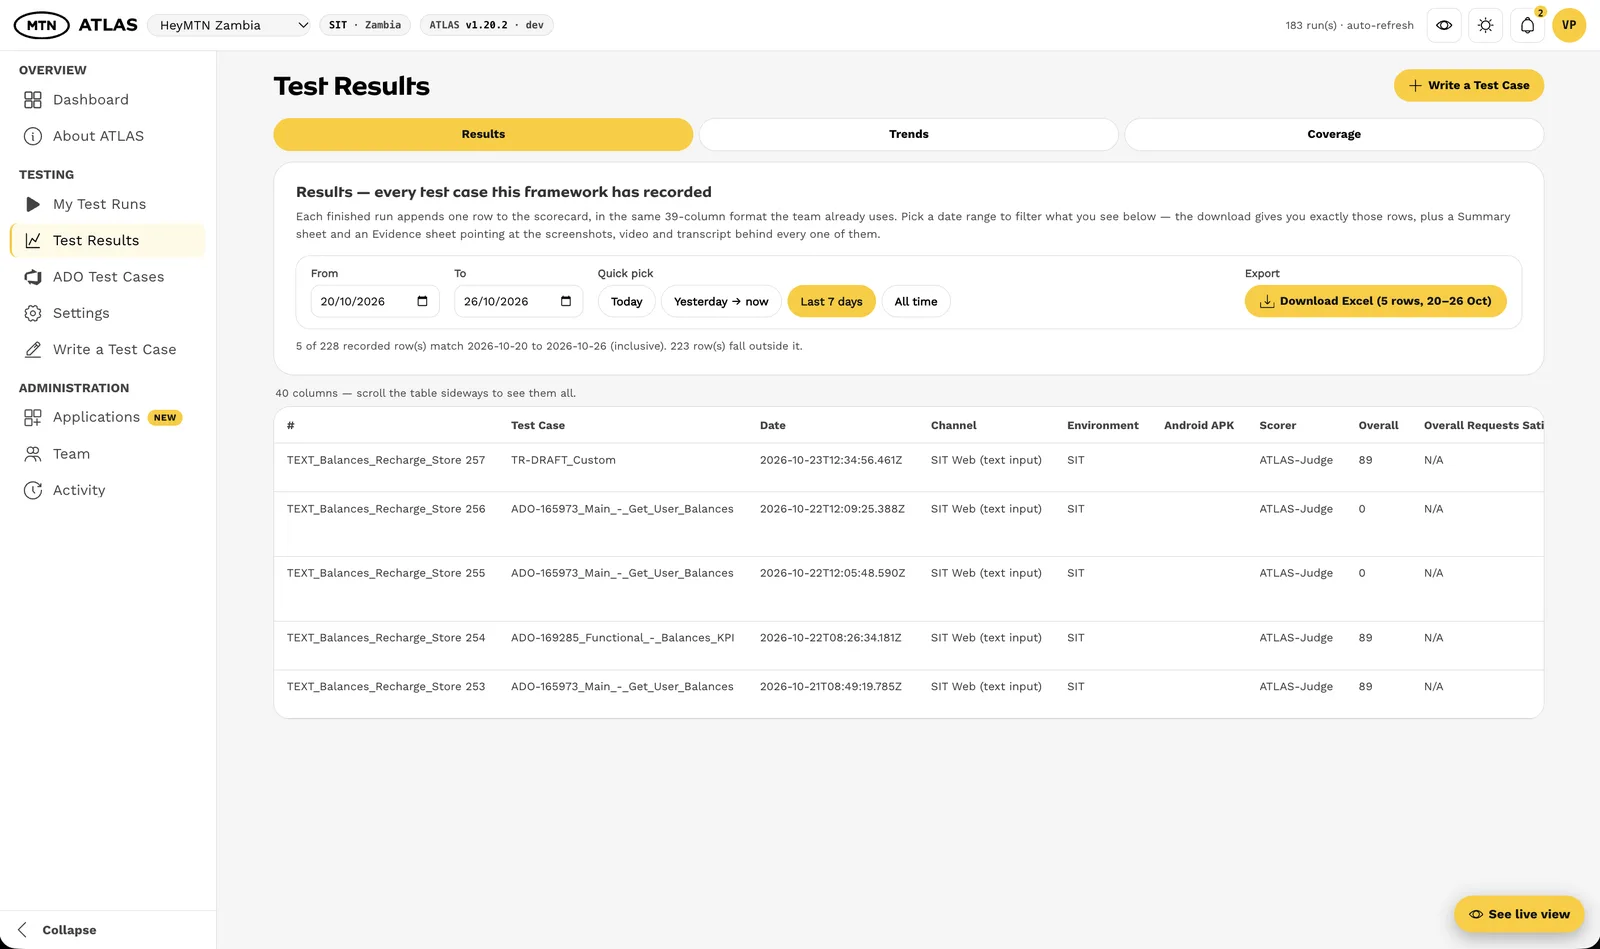
ATLAS test results view with scorecard rows and Excel export

Project Specifications

IndustryTelecom / Mobile
RegionAfrica
SurfacesWeb app & Android

Specific Business Problems

  • Hundreds of manual test cases per release, each needing OTP sign-in, a conversation and a careful look at the answer.
  • Non-deterministic AI answers caused false failures in string-matching scripts.
  • Rich UI such as balance tiles, catalogues and purchase cards had to match expected designs, not just text.
  • Every result had to land on the right Azure DevOps case with step-level evidence, under strict security rules.

Objectives

Test an AI assistant the way a person would, at release speed.
Specific Goals & KPIs

  • Run any case as written, including new wording, without rewriting it for the tool.
  • Judge each expected result by meaning and by what the screen shows.
  • Report tool problems as “could not test”, so a FAIL always points at the product.
  • Post every verdict back to Azure DevOps with step results and evidence.
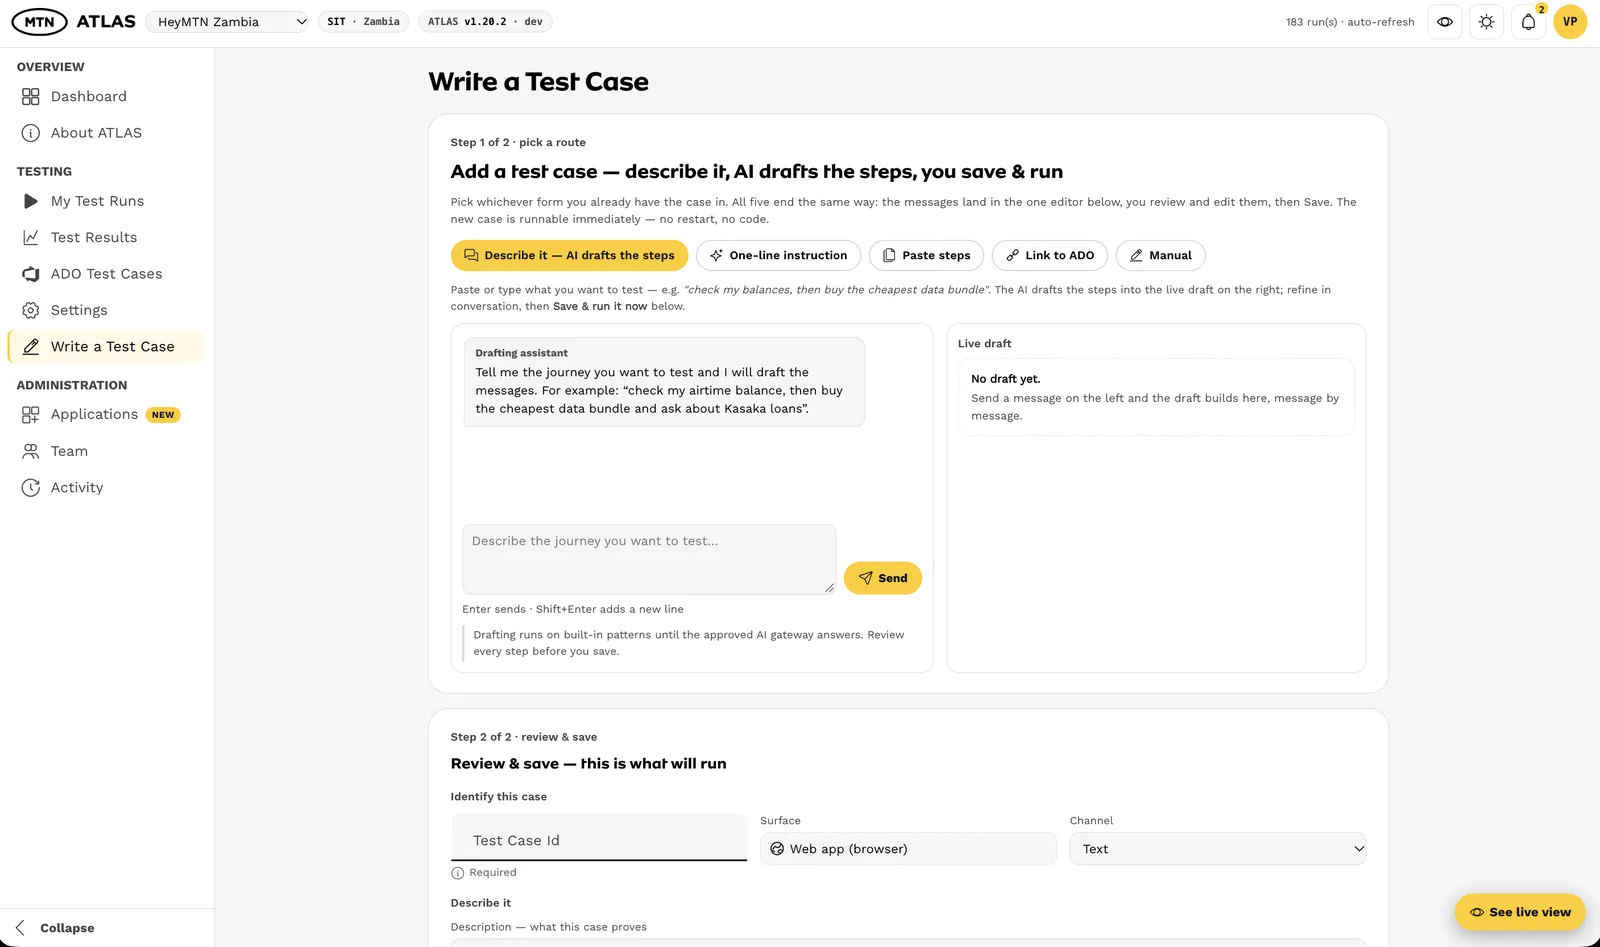
ATLAS Write a Test Case screen where AI drafts the steps

AI Functionality

  • Agentic executor reads the live screen, plans the next action and acts, trying another route when a control does nothing.
  • Vision judge scores each acceptance criterion against captured screens and expected screenshots.
  • Consensus and bias guards hold inconsistently judged criteria for review instead of guessing.
  • Case understanding turns Gherkin, shared steps and parameter tables into runnable turns.

Impact of Challenges

  • Manual execution could not keep pace with the release cadence.
  • Script-based automation broke whenever wording or layout changed.
  • UI defects and stalled replies were easy to miss without evidence.
  • Testers spent their time on execution instead of findings.

Proposed Solution

  • Generate into the client's framework: cases stay in Azure DevOps and results go back to the same test points.
  • One engine for two surfaces: web through a real browser, Android on an emulator.
  • Agentic execution with a scripted fallback, and deterministic guards around the AI.
  • Multi-tester platform with roles, per-tester tokens and a full audit trail.
TypeScript · Node.js
React
Playwright
Appium
Vision LLM
Docker · Helm · AKS
ATLAS dashboard with pass and fail counts, runs by channel and most-run test cases
ATLAS test case authoring with live draft

Customization Highlights

  • Shared steps and parameter tables resolved into the exact messages each case names.
  • Real OTP sign-in per tester, with codes and numbers never written into evidence.
  • Design checks against expected screenshots attached to the case.
  • Honest “could not test” reporting with the reason, never a false product FAIL.

Implementation

Process Overview

Weeks 1–3

One case, end to end. A single balance-check case run on the real app, end to end.

Weeks 4–6

Agentic driving and a fair judge. AI agent and criterion-by-criterion judge; web and Android at parity.

Weeks 7–8

Every case, every plan. All test plans imported and run; every tool fault fixed generically.

Weeks 9–10

A platform for the team. Hosted for many testers, results posted back step by step.

Timeline and Milestones

First end-to-end case demonstrated

All test plans imported and run

Multi-tester platform live on the client's cluster

Execution

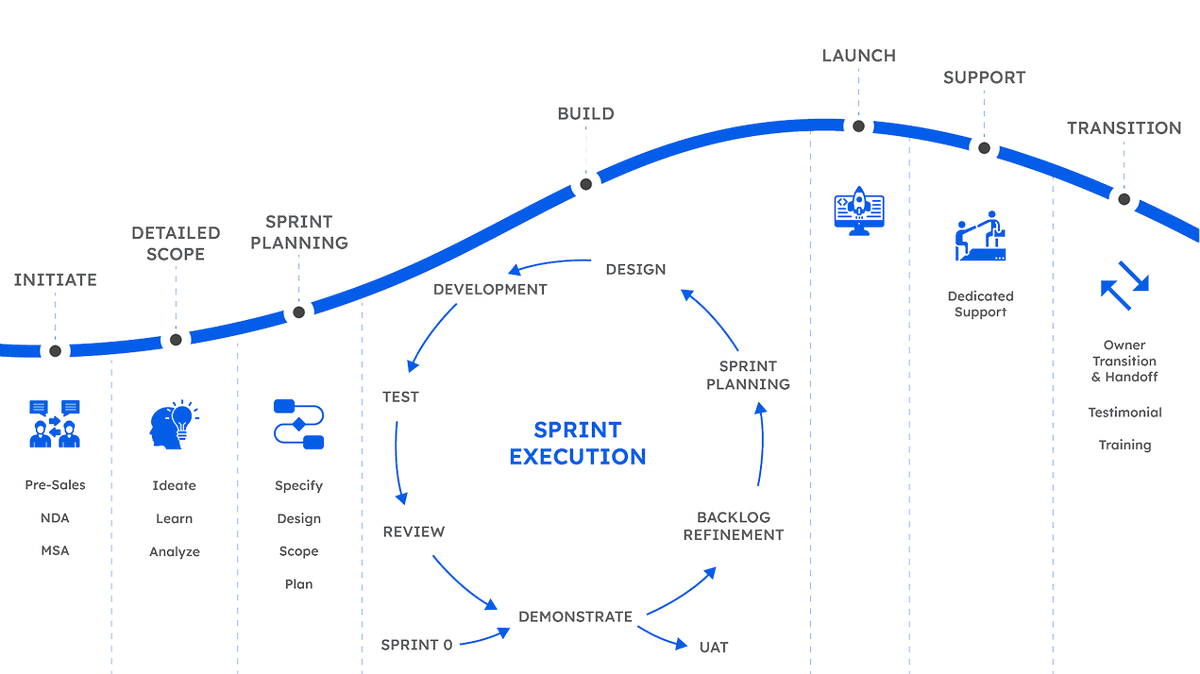
Delivered in short, verified increments on real cases from the client's plans.

Run, inspect every verdict, fix the cause generically and re-run. Every fix shipped with a regression test, and every release passed the client's CI gates.
Agile Development Process

Quantitative Results

313Cases across 10 plans run end to end in one regression
3.9%Tool-caused failed runs, down from 7.8%
3 sAutomated OTP sign-in, down from 30 s

Qualitative Results

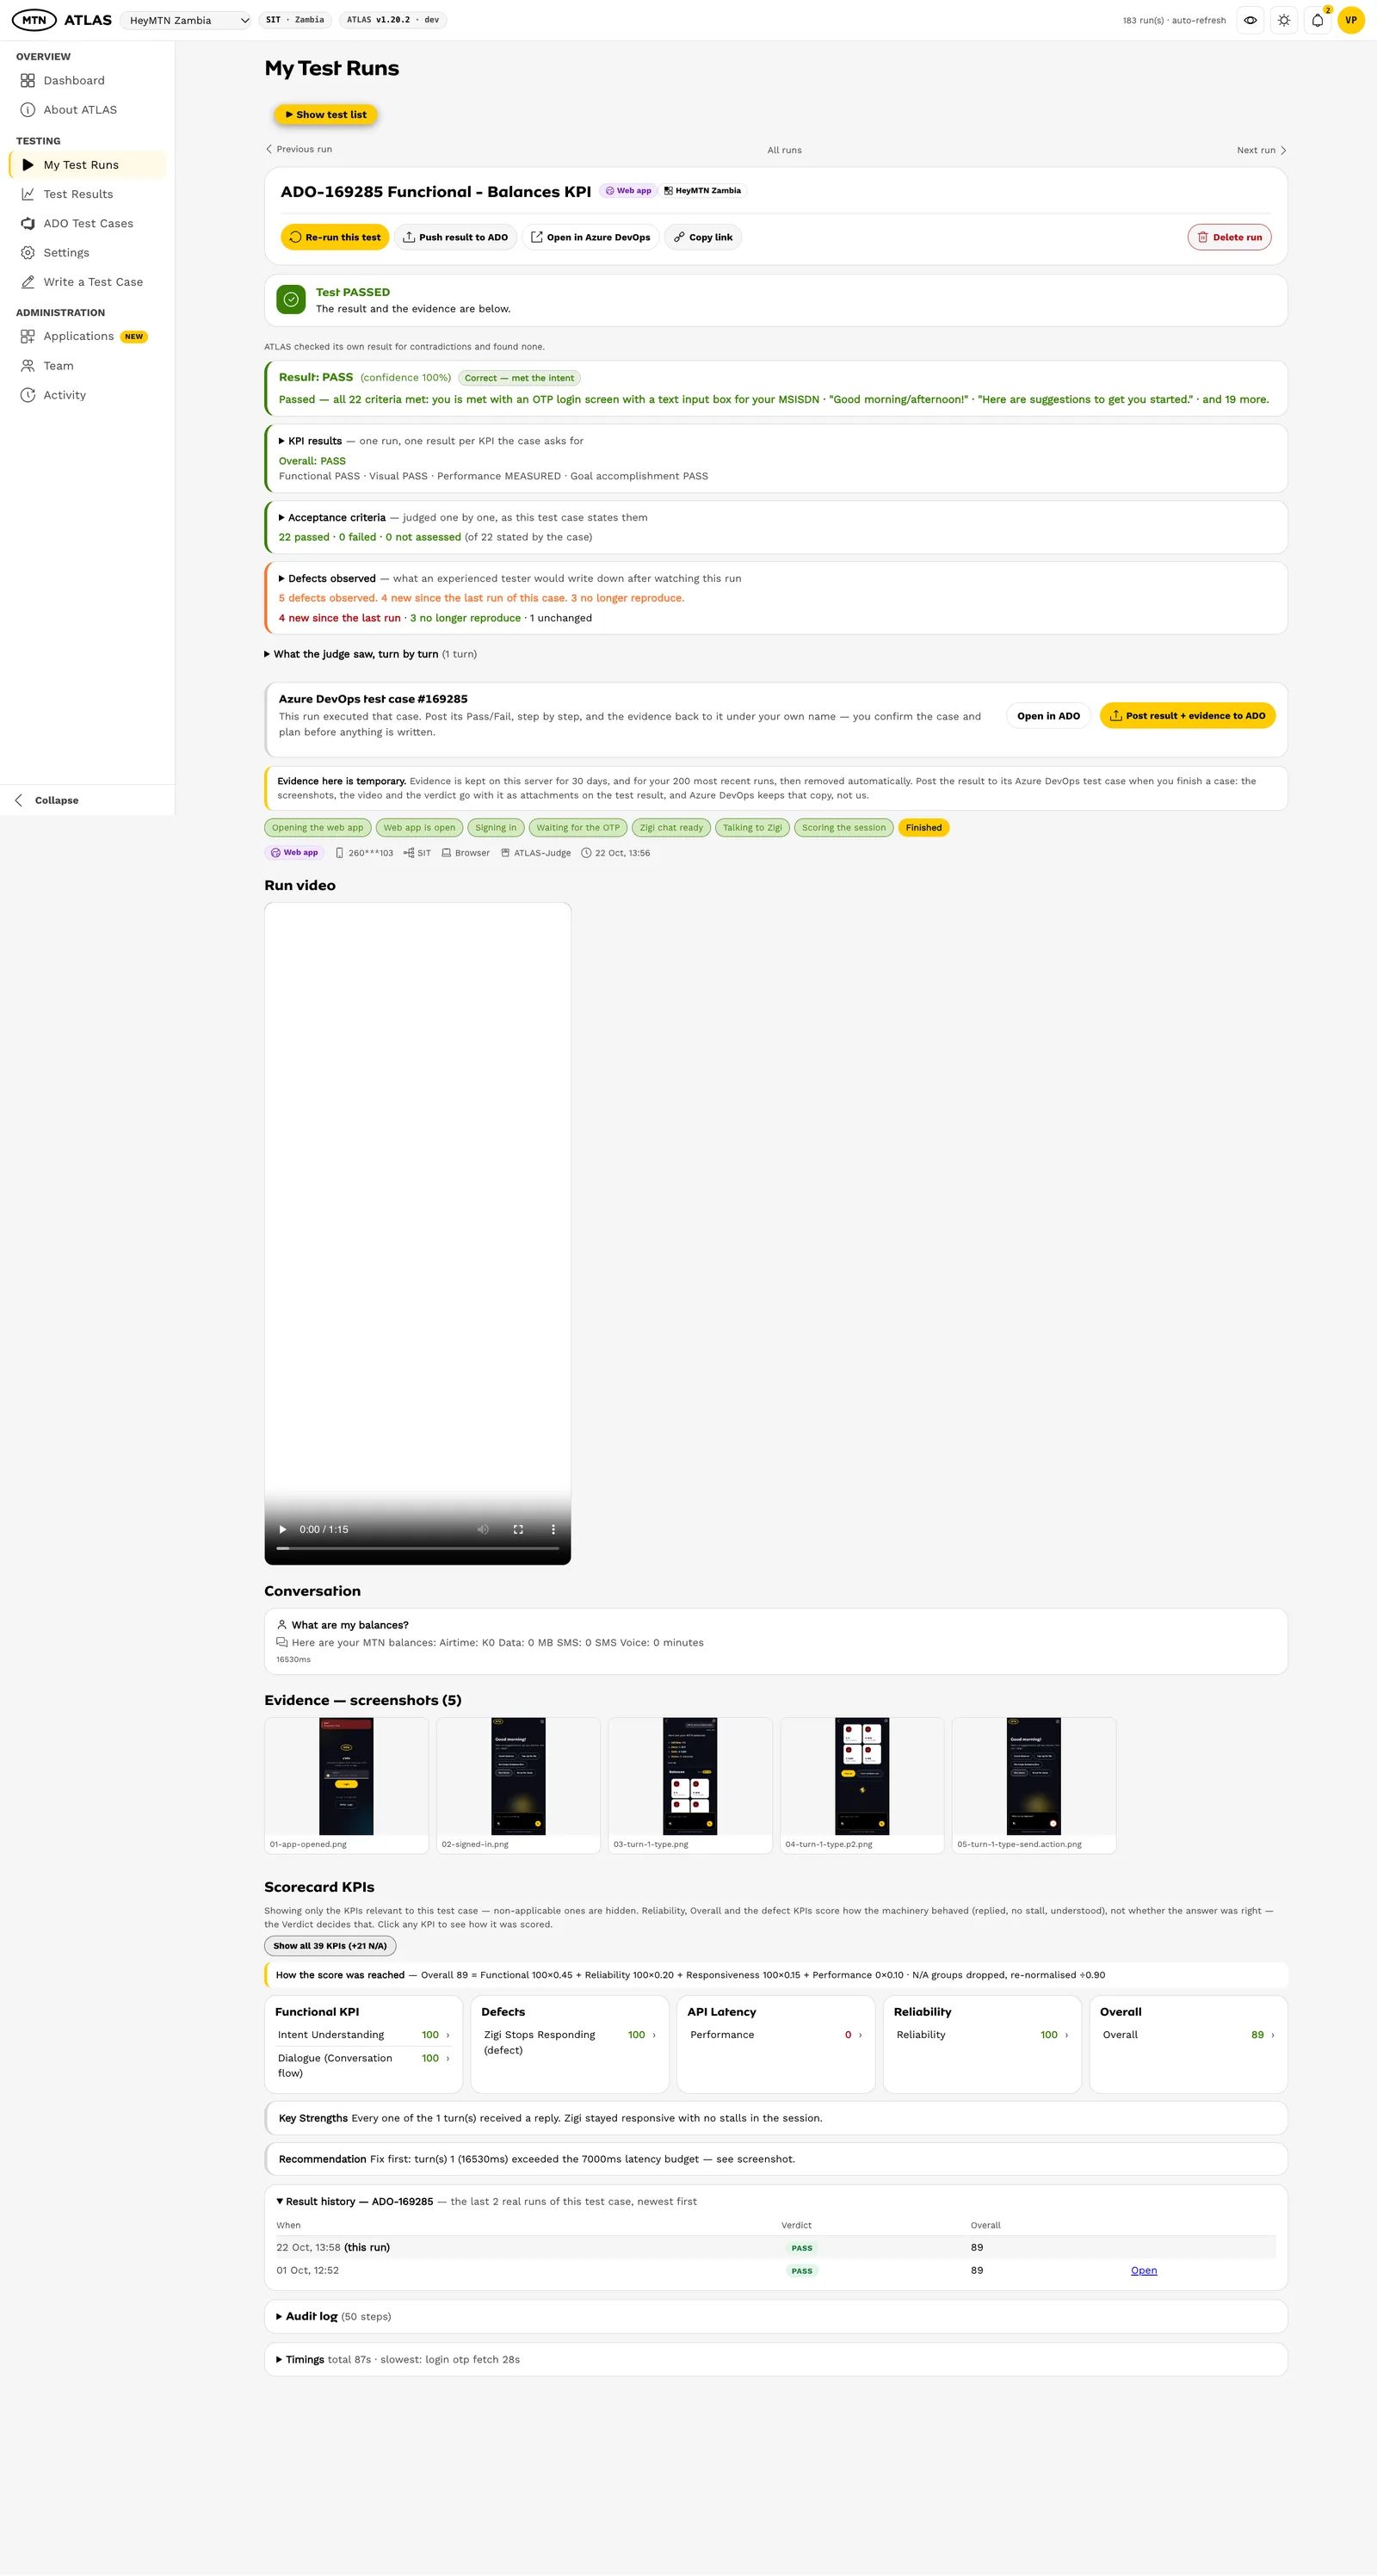
  • Testers review findings, not screens, with screenshots, video and reasons for every criterion.
  • New cases run on day one without rewriting.
  • A FAIL means the product, because tool faults are reported as “could not test”.
  • Secure by default: approved model gateway only, no credentials or customer numbers in artefacts.
ATLAS test run detail with verdict, acceptance criteria, evidence and scorecard KPIs

Want to Automate Testing of Your AI Product?

We build agentic test platforms that read your test cases, drive your real apps and judge results the way your testers would.

Trusted by global partners

NUS Safaricom Intuify Solvit i-banq Fractal